|
Ziyang Xu / 徐子扬 Hi, I am a Ph.D. student in Information and Communication Engineering at the School of Electronic Information and Communications (EIC), Huazhong University of Science and Technology (HUST, 华中科技大学), advised by Professors Xinggang Wang and Wenyu Liu. I began my Ph.D. studies in September 2025. Prior to this, I received my M.E. degree in Information and Communication Engineering from EIC, HUST (华中科技大学) in 2025, and my B.E. degree in Information Engineering from the School of Information Engineering (IE), Wuhan University of Technology (WHUT, 武汉理工大学) in 2022. My research spans visual generation & perception & memory, multimodal world generation, and AI for science. Email | Google Scholar | GitHub | ORCID | X | WeChat Latest Update: October 1, 2026 |
|
News[2026.10] XS-VID is accepted to IEEE TPAMI.
[2026.09] I am named an Outstanding Ph.D. Student at Huazhong University of Science and Technology.
[2026.06] Moebius is accepted to ECCV 2026.
[2026.01] GenDSA-V2 is published in Nature Medicine.
[2025.09] Genesis is accepted to NeurIPS 2025.
[2025.01] GenDSA is published in Med (Cell Press).
[2025.01] GaraMoSt is accepted to AAAI 2025.
[2024.10] I receive the National Scholarship for Graduate Students (Master’s Level).
|
HighlightPixelHacker and Moebius, my first/co-first-authored image inpainting projects, both achieved the No. 1 daily ranking on Hugging Face.
An early quantized on-device image inpainting model that I developed during my internship at vivo AI Lab—predating PixelHacker and Moebius, and related to the later PixelHacker line of work—has been rolled out across vivo’s full smartphone lineup, serving 400 million active users worldwide. You can find it in Gallery under AI Retouching → AI Eraser.
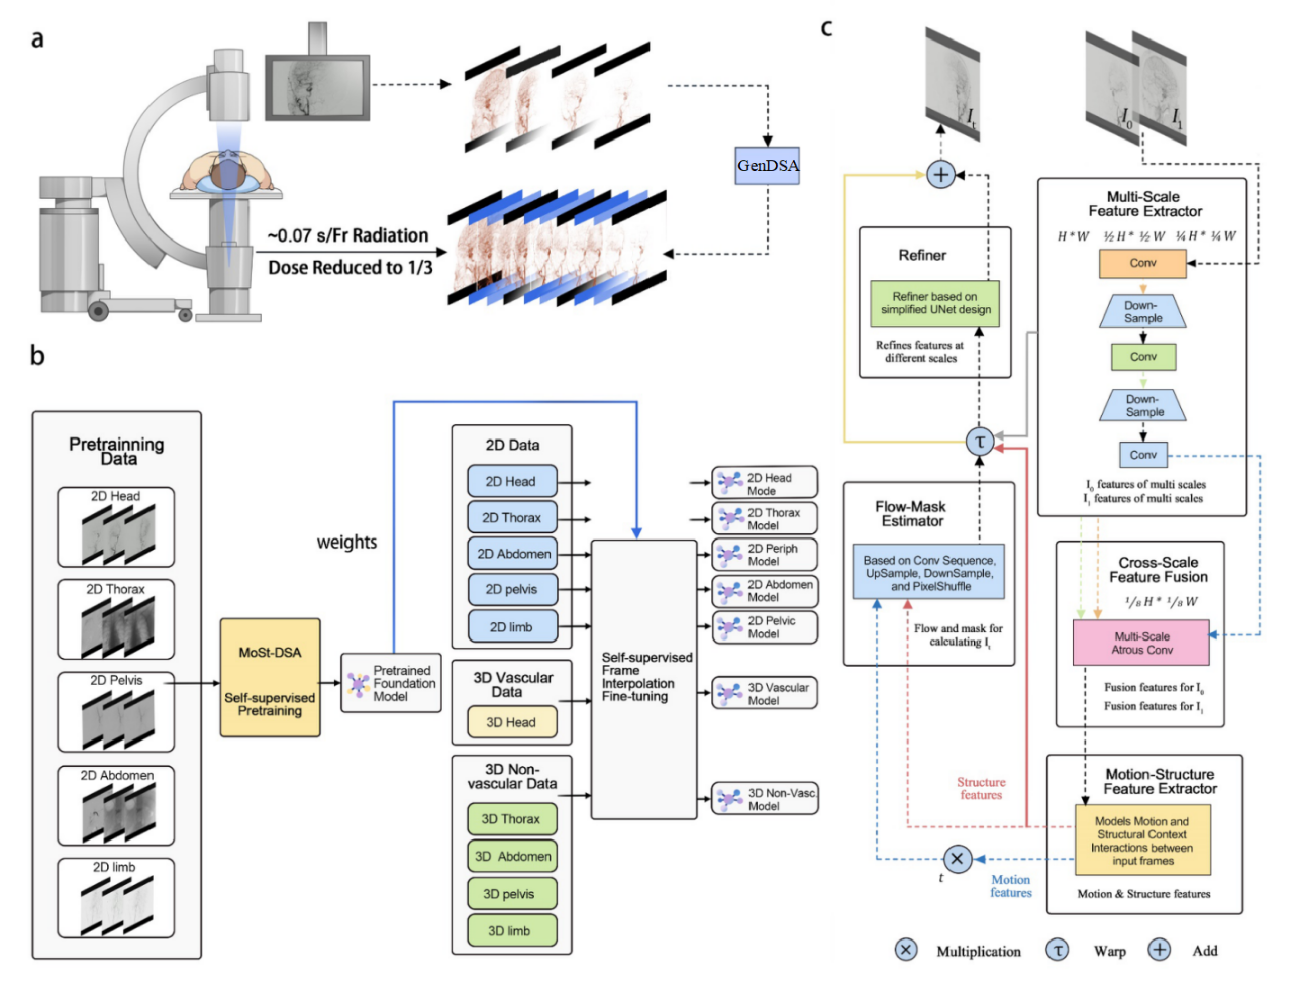
My research on multi-frame generative low-dose DSA (Digital Subtraction Angiography) imaging spans MoSt-DSA, GaraMoSt, GenDSA, and GenDSA-V2, with results published in ECAI, AAAI, Med (Cell Press), and Nature Medicine. This line of work contributes to a National Key R&D Program of China and has advanced from algorithm development to clinical validation and medical-device integration. More than 100,000 patients worldwide undergo DSA-guided procedures every day. In a completed prospective randomized controlled trial involving 1,068 patients, GenDSA-V2 reduced radiation exposure for patients and healthcare professionals by approximately two-thirds. Clinical trial registration: ChiCTR2400084789.
As of September 1, 2026, my open-source research projects have received 1,150+ GitHub stars and 110+ forks in total, with a single project reaching 580+ stars.
|
ResearchMy research proposes efficient, high-performance and reliable generative and perceptual models for complex visual challenges, spanning image inpainting, multimodal world generation, small-object video understanding, and AI-enabled low-dose medical imaging. Across these areas, I focus on structural, temporal, and cross-modal consistency, practical efficiency, and real-world impact. Publications are grouped by research theme; my name is bolded, * denotes equal contribution, and † denotes project leadership. |
1/3 Efficient & High-Performance Visual Generation and Image InpaintingI study efficient and high-performance image generation methods that preserve structural and semantic fidelity without relying on model scaling, spanning consistency-aware diffusion inpainting and knowledge-distilled lightweight systems for practical deployment. |
|
|
Representative Work
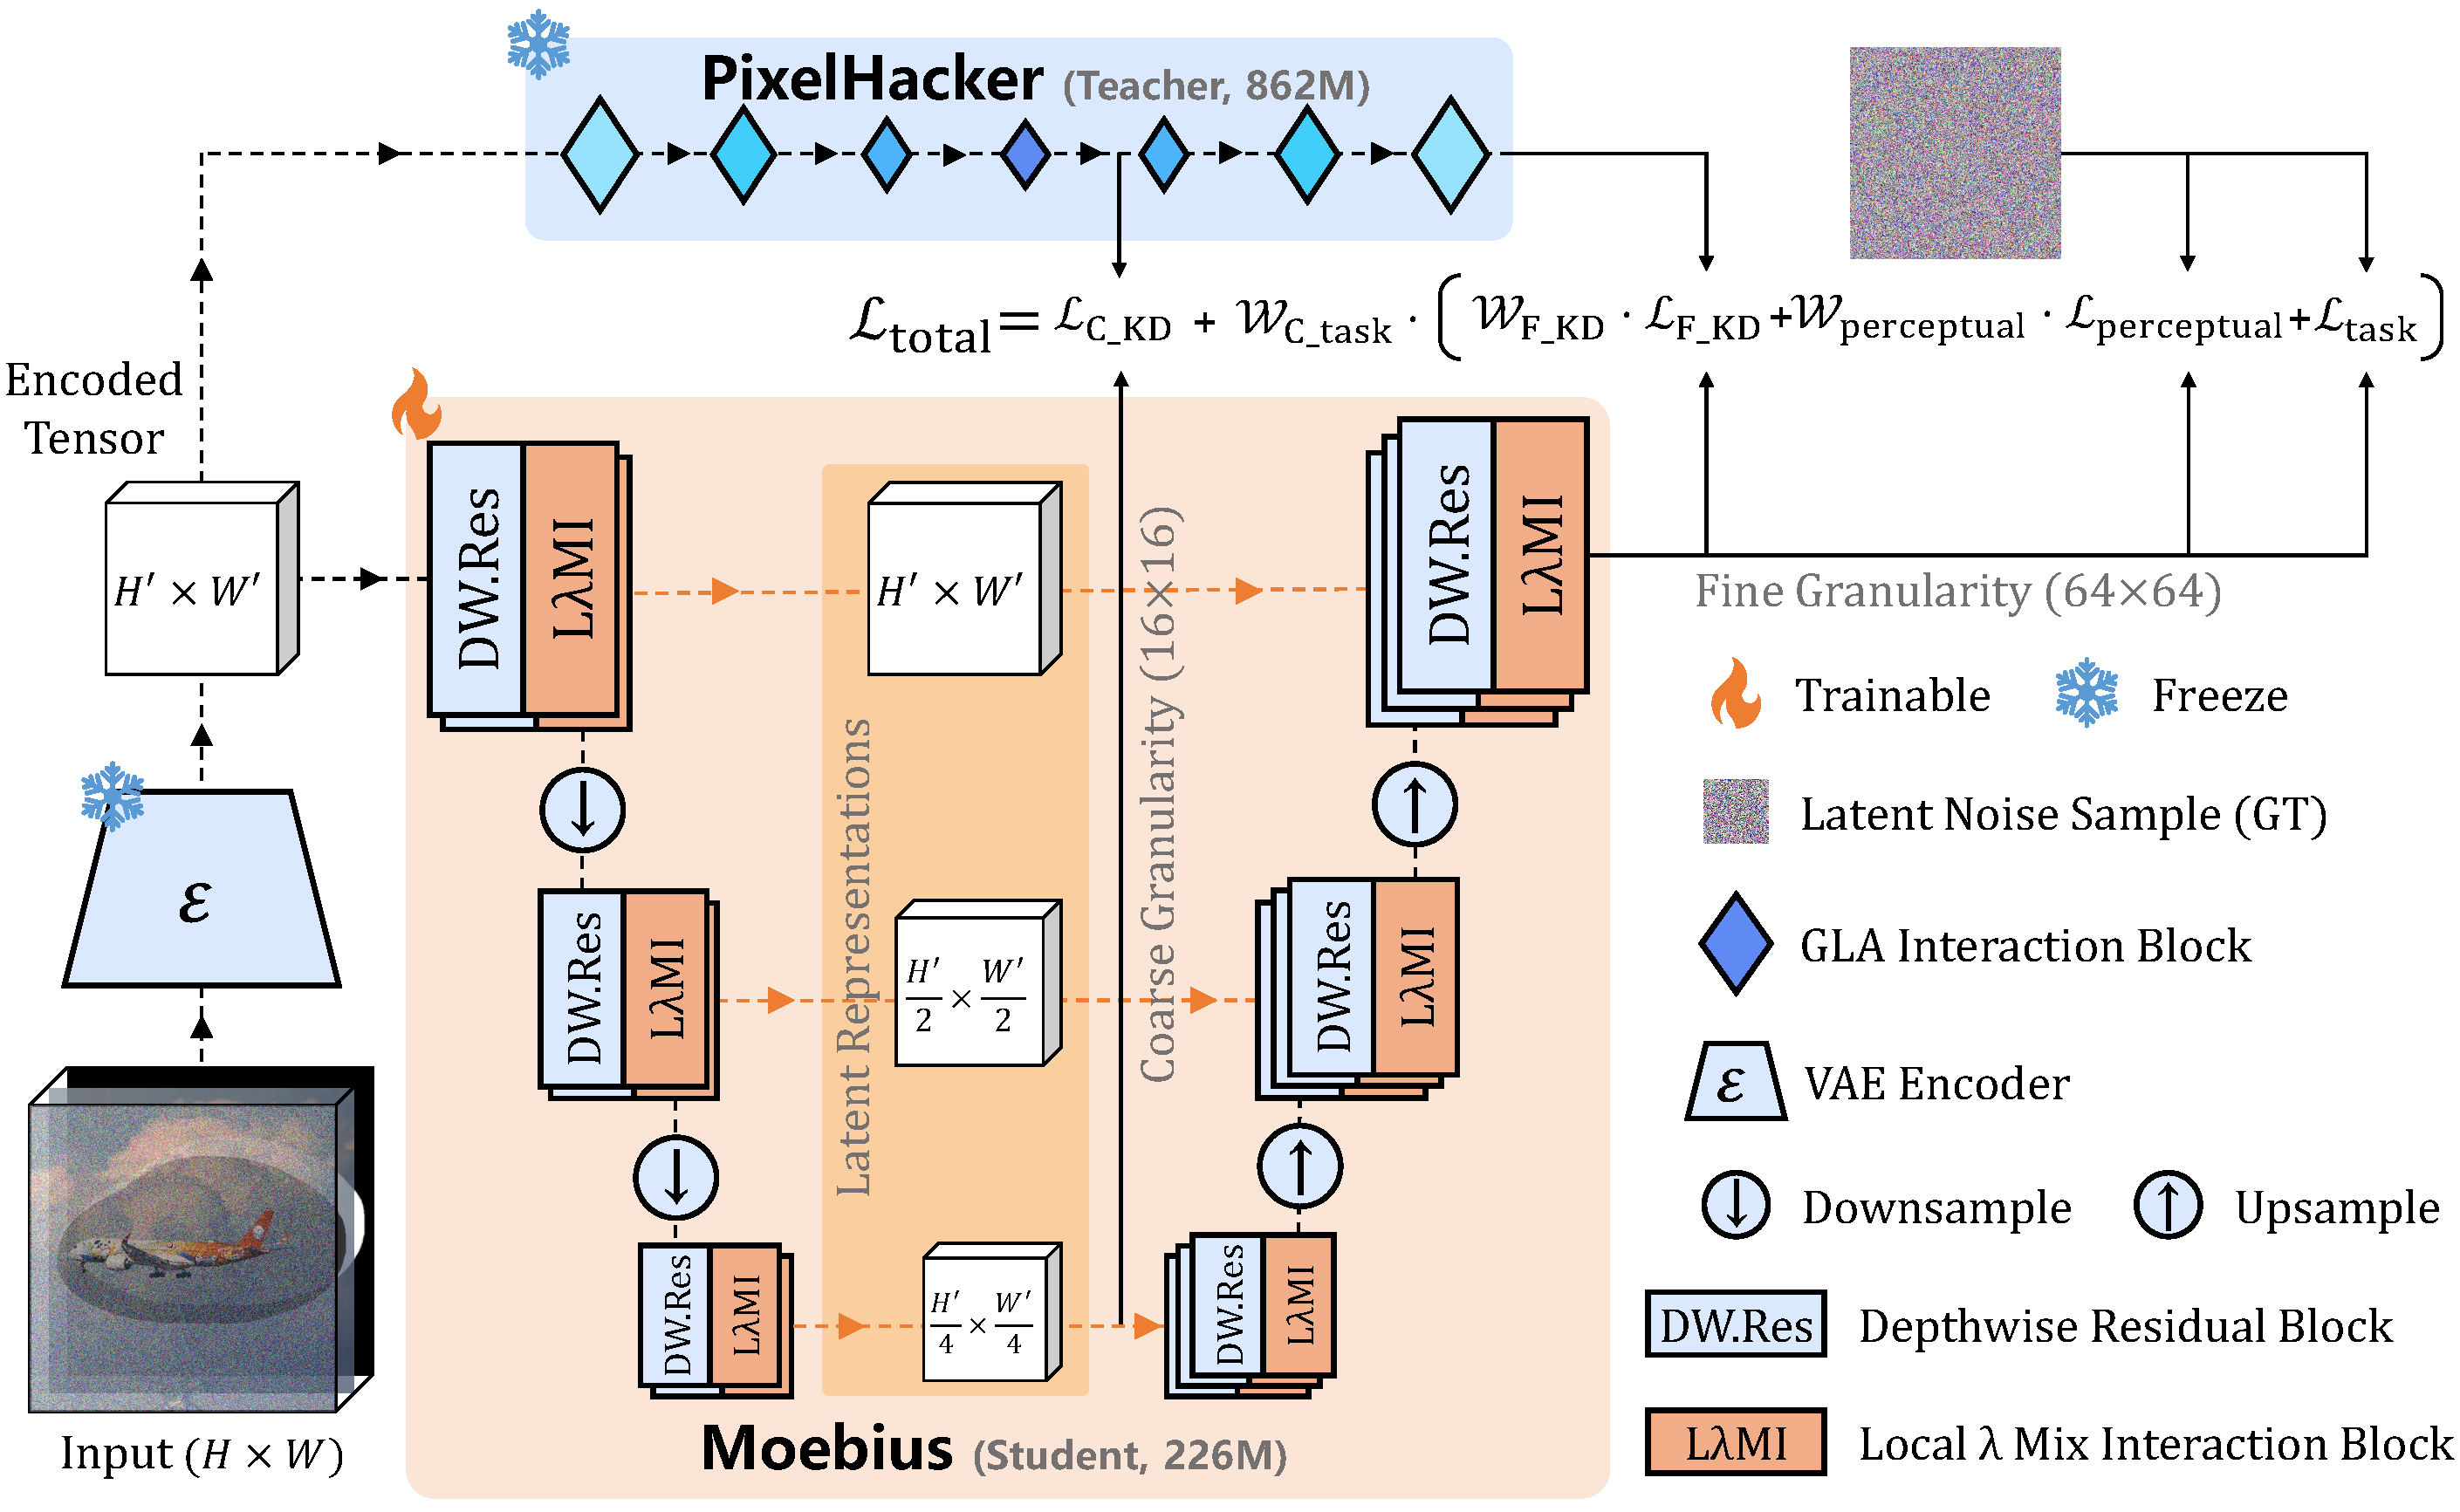
Moebius: 0.2B Lightweight Image Inpainting Framework with 10B-Level Performance* Equal contribution; † project leadership
Role: Co-first Author · Project Lead
This work was completed while Ziyang Xu and Kangsheng Duan were research interns at vivo AI Lab.
Moebius extends the PixelHacker line of work by asking whether high-quality image inpainting requires continued model scaling. It combines a compact architecture with knowledge distillation, using only 0.22B parameters—less than 2% of FLUX.1-Fill-Dev—while matching or surpassing it across six natural and portrait benchmarks and reducing total inference time by more than 15×. |
|
Representative Work
PixelHacker: Image Inpainting with Structural and Semantic Consistency† Project leadership
Role: First Author · Project Lead
This work was completed while Ziyang Xu and Kangsheng Duan were research interns at vivo AI Lab.
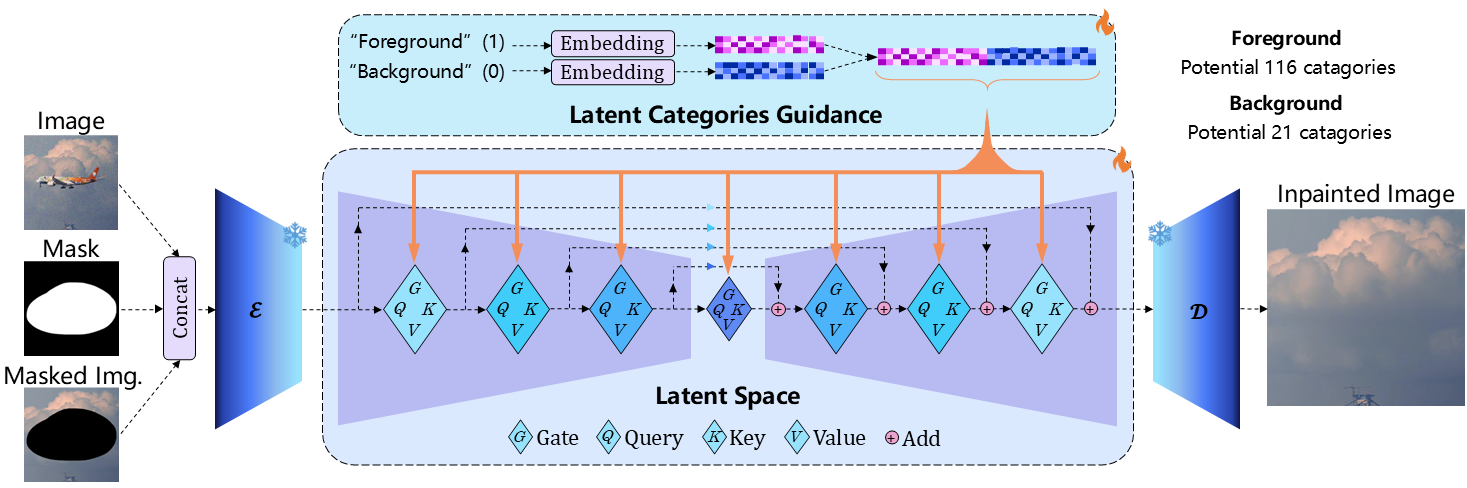
PixelHacker introduces Latent Categories Guidance (LCG), which separately models foreground and background semantic distributions and injects them into diffusion-based denoising. Trained with 14 million image-mask pairs, it improves structural and semantic consistency across natural and portrait inpainting benchmarks while remaining substantially smaller and faster than large industrial baselines. |
2/3 Multimodal World Generation and Visual PerceptionI study generation and perception in complex dynamic scenes: Genesis models spatio-temporally and cross-modally coherent video–LiDAR worlds, while XS-VID advances small object detection and tracking through large-scale data, unified benchmarks, and efficient temporal modeling. |
|
|
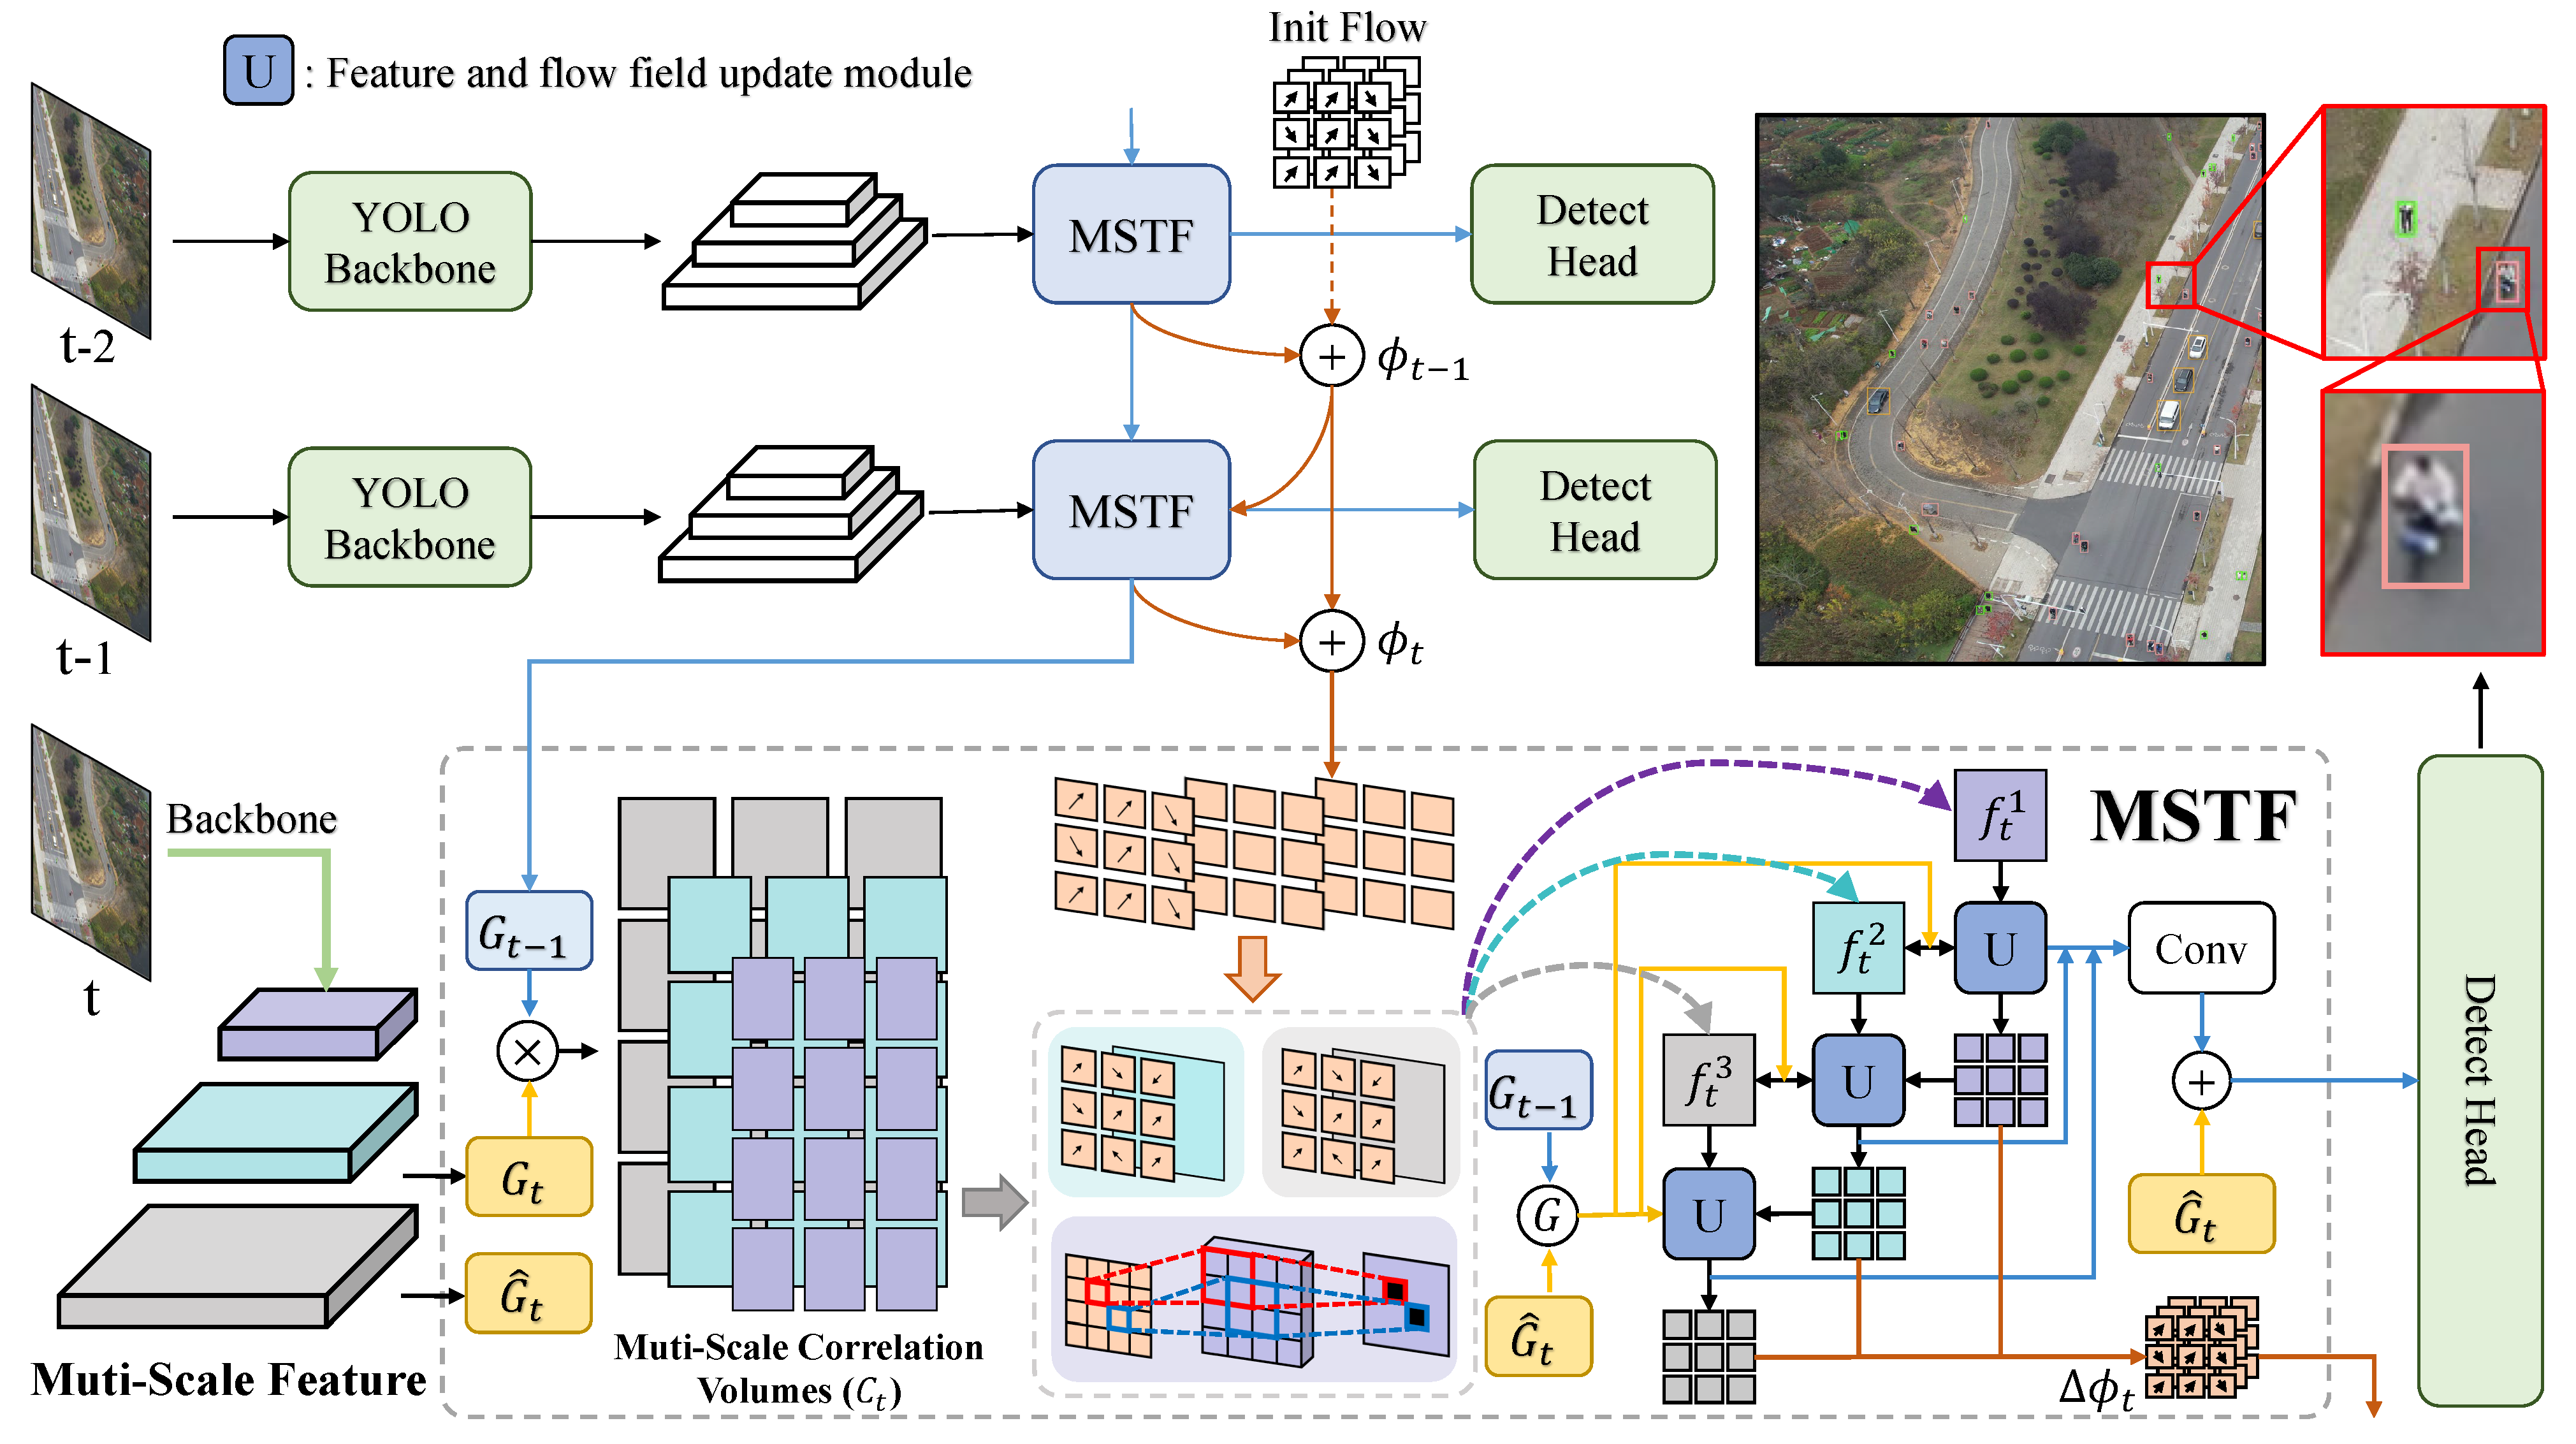
XS-VID: A Large-Scale Benchmark for Small Object Detection and Tracking in VideosXS-VID establishes a large-scale, densely annotated benchmark for small object detection and tracking in videos, unifying Detection, MOT, and SOT across 374 sequences, 223K frames, and 1.4M bounding boxes. Its challenging scale regime, standardized protocols, and efficient YOLOFT baseline provide a rigorous, reproducible foundation for advancing video understanding at the smallest scales. |
|
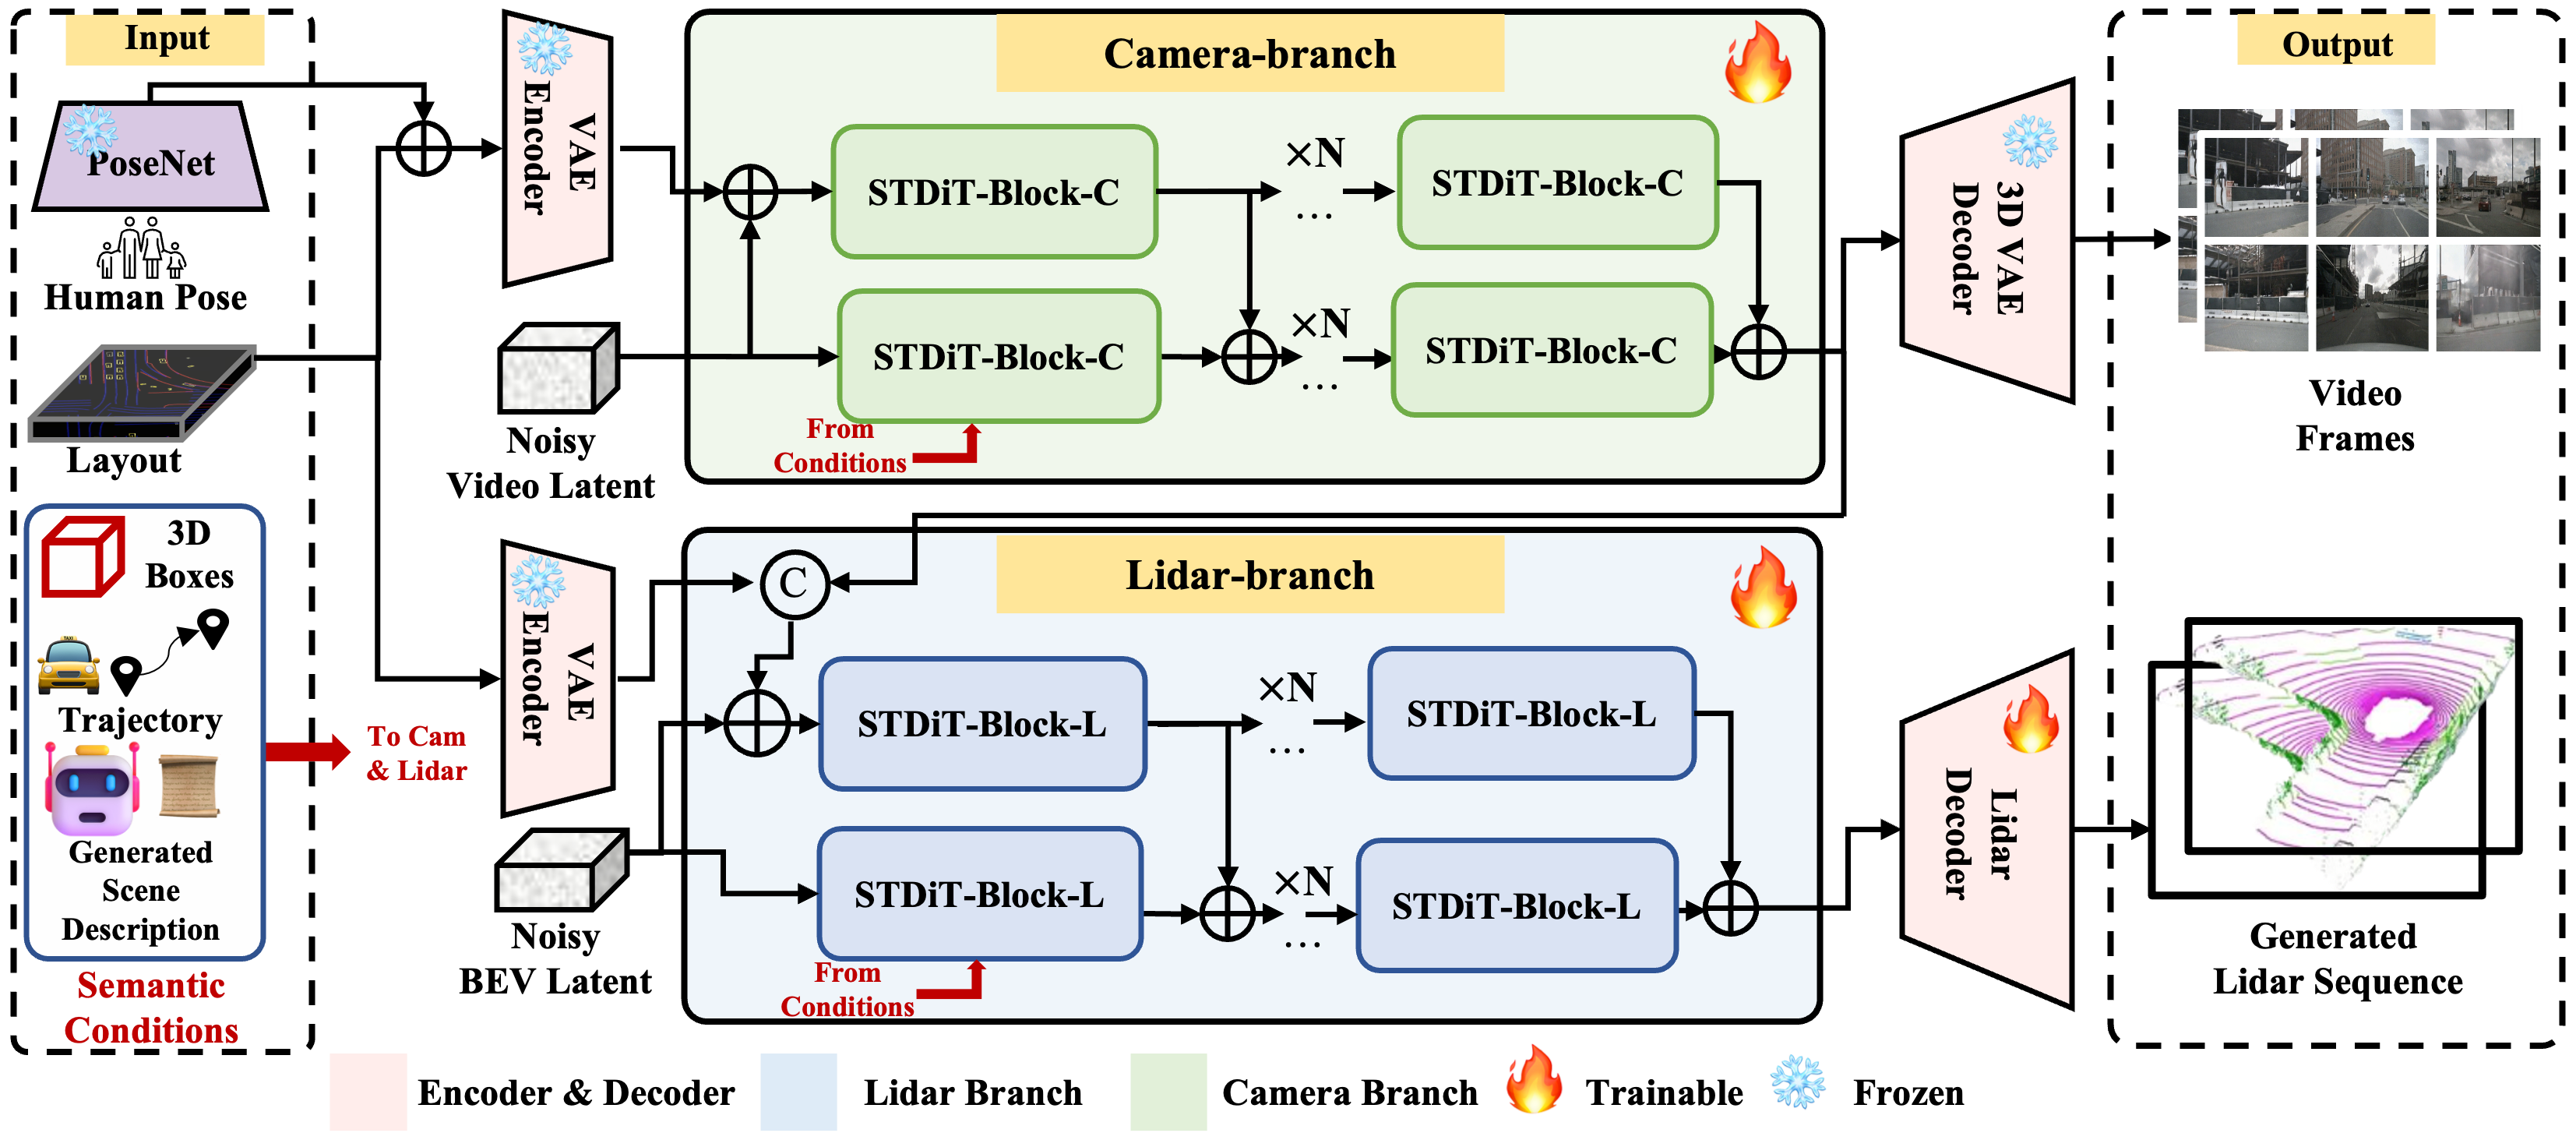
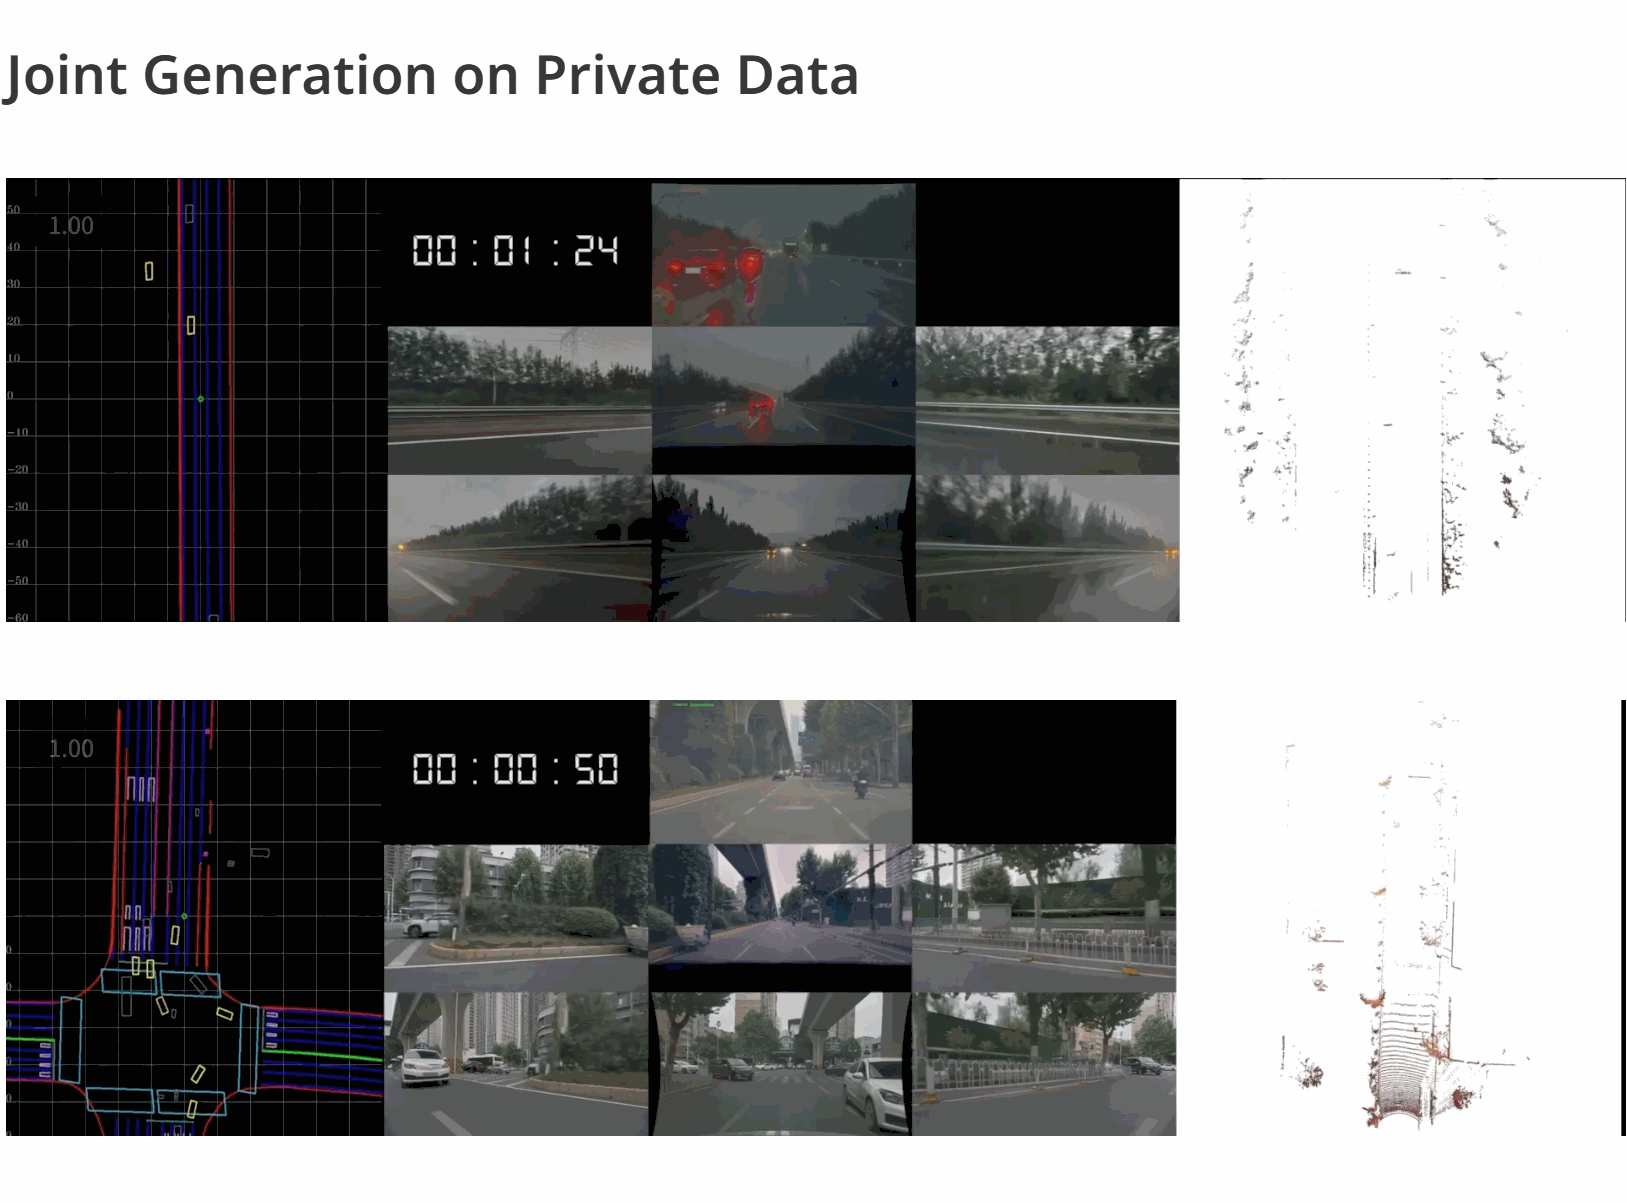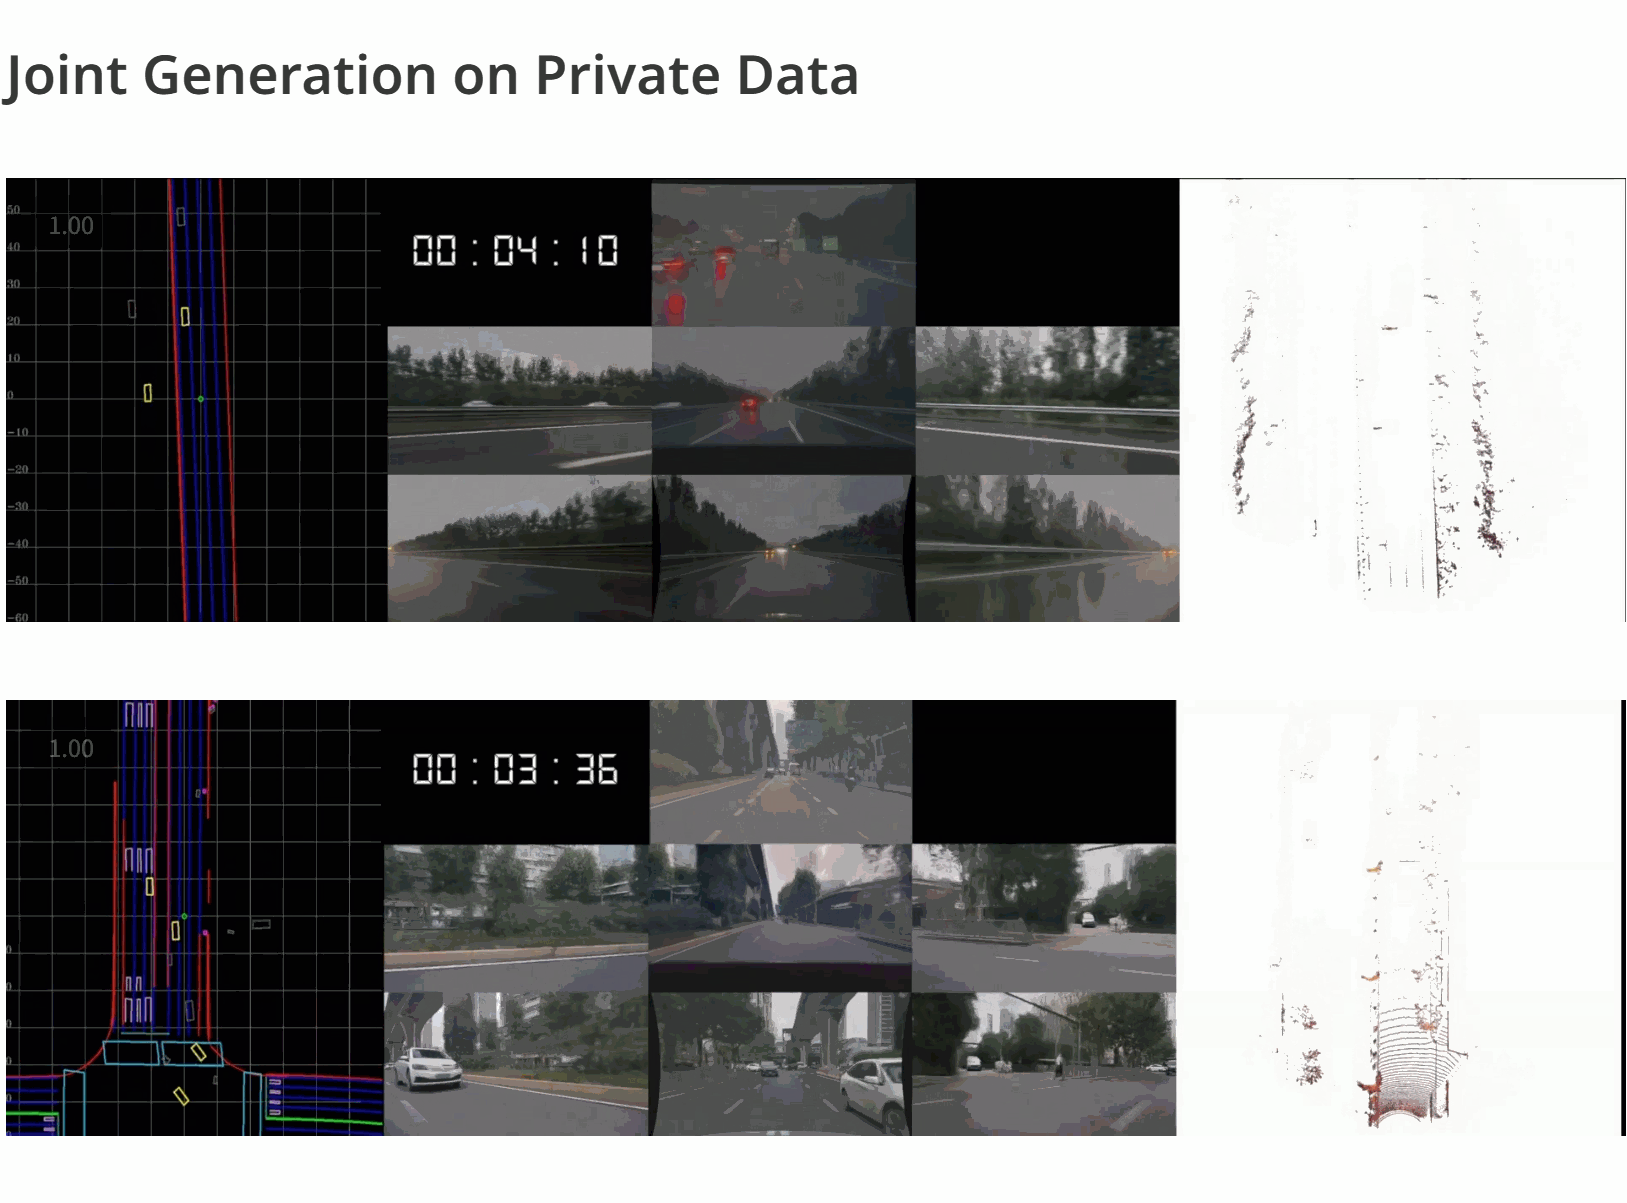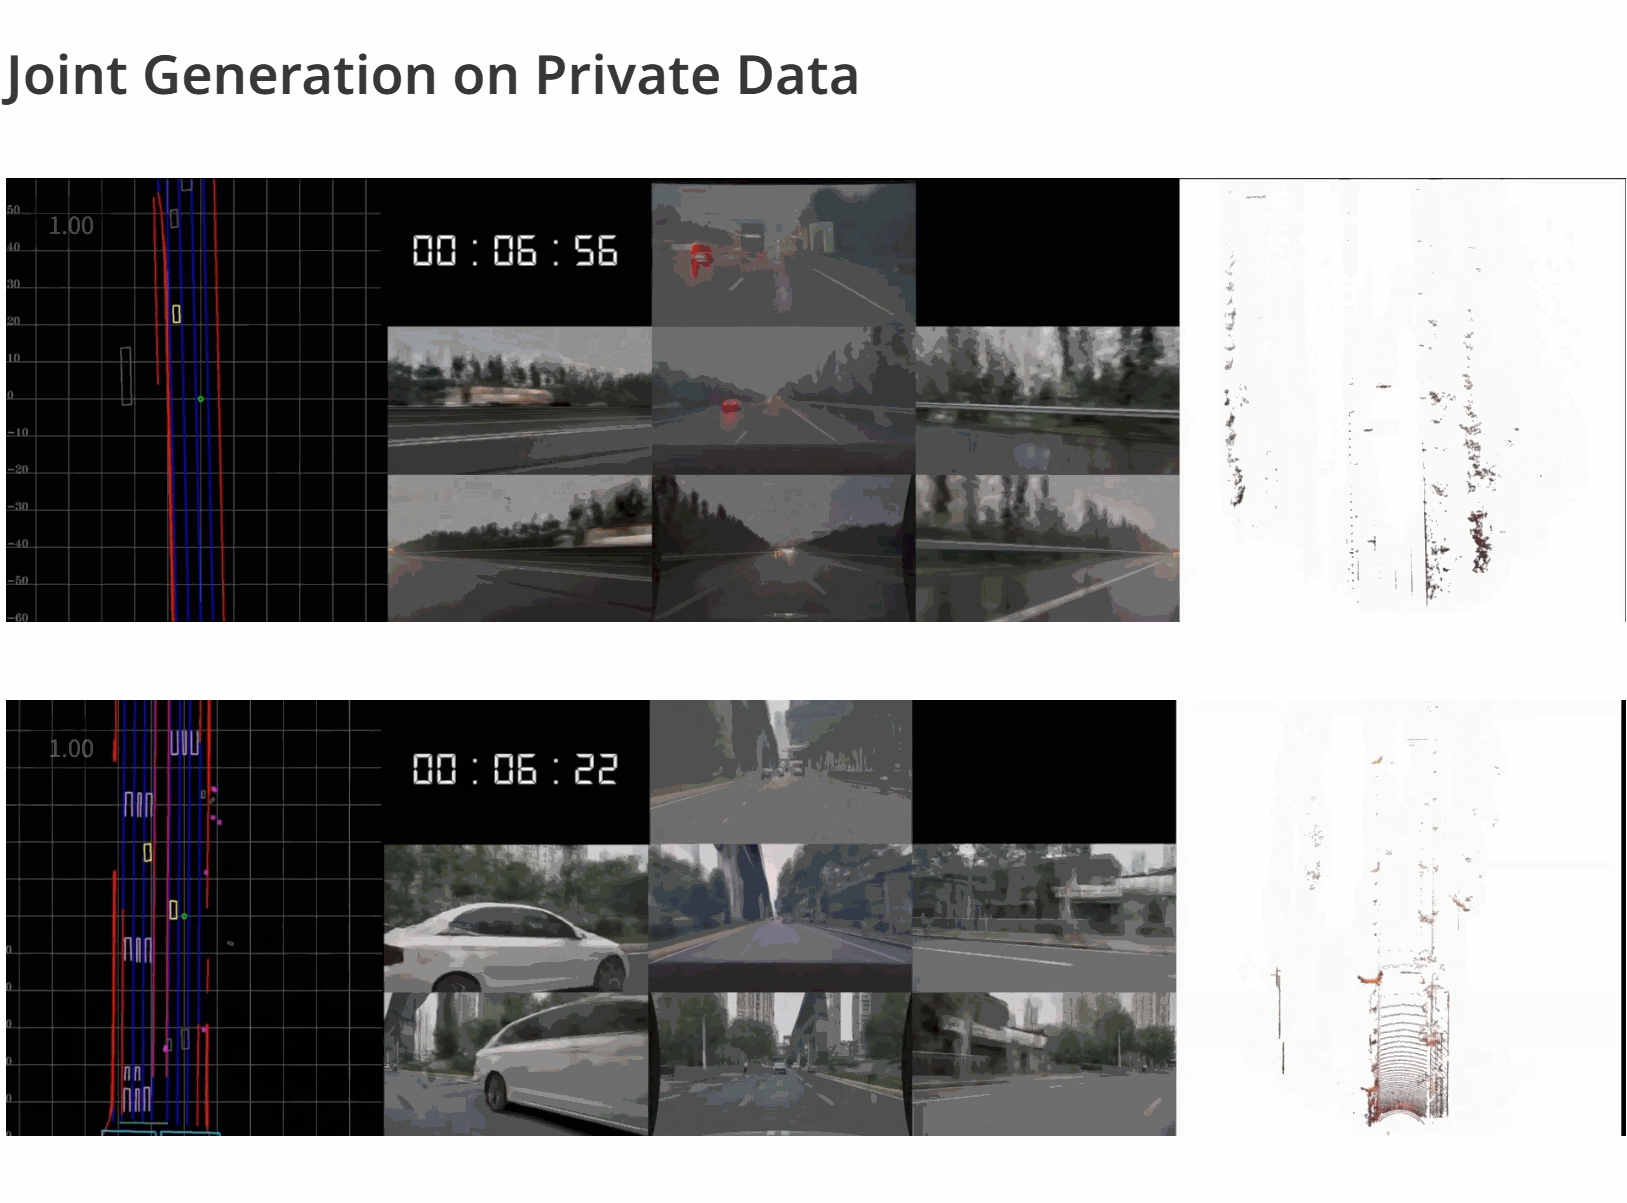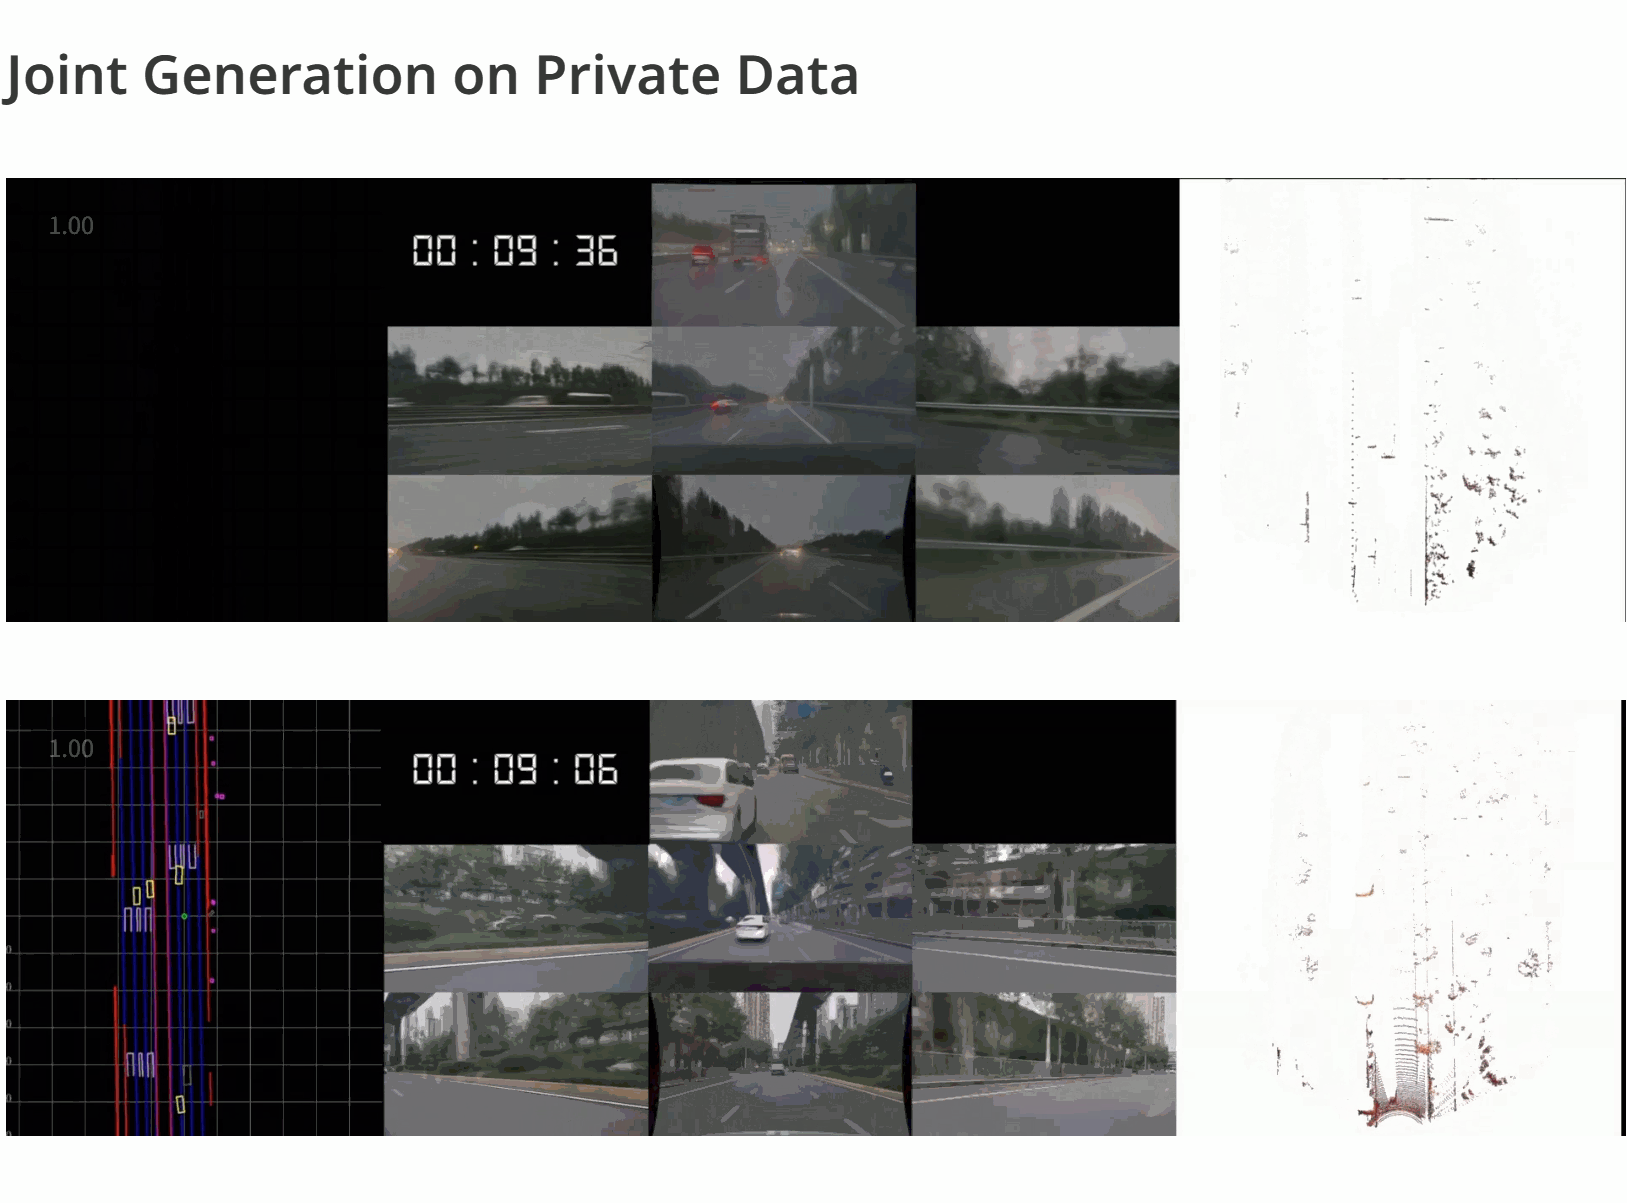
Genesis: Multimodal Driving Scene Generation with Spatio-Temporal and Cross-Modal Consistency* Equal contribution
Genesis jointly generates multi-view driving videos and LiDAR sequences with spatio-temporal and cross-modal consistency. It couples a DiT-based video diffusion model and a BEV-aware LiDAR generator through a shared latent space, achieving strong generation results on nuScenes and improving downstream segmentation and 3D detection. |
3/3 AI4S (Generative Low-Dose DSA Imaging, Video Multi-Frame Interpolation)I translate generative modeling into safer low-dose DSA imaging, advancing from motion-structure-aware multi-frame interpolation to large-scale pretraining, multi-center validation, and prospective randomized clinical evaluation of real-world radiation reduction. |
|
|
Representative Work
Generative AI-based low-dose digital subtraction angiography for intra-operative radiation dose reduction: a randomized controlled trial* Equal contribution
Role: Algorithm Lead
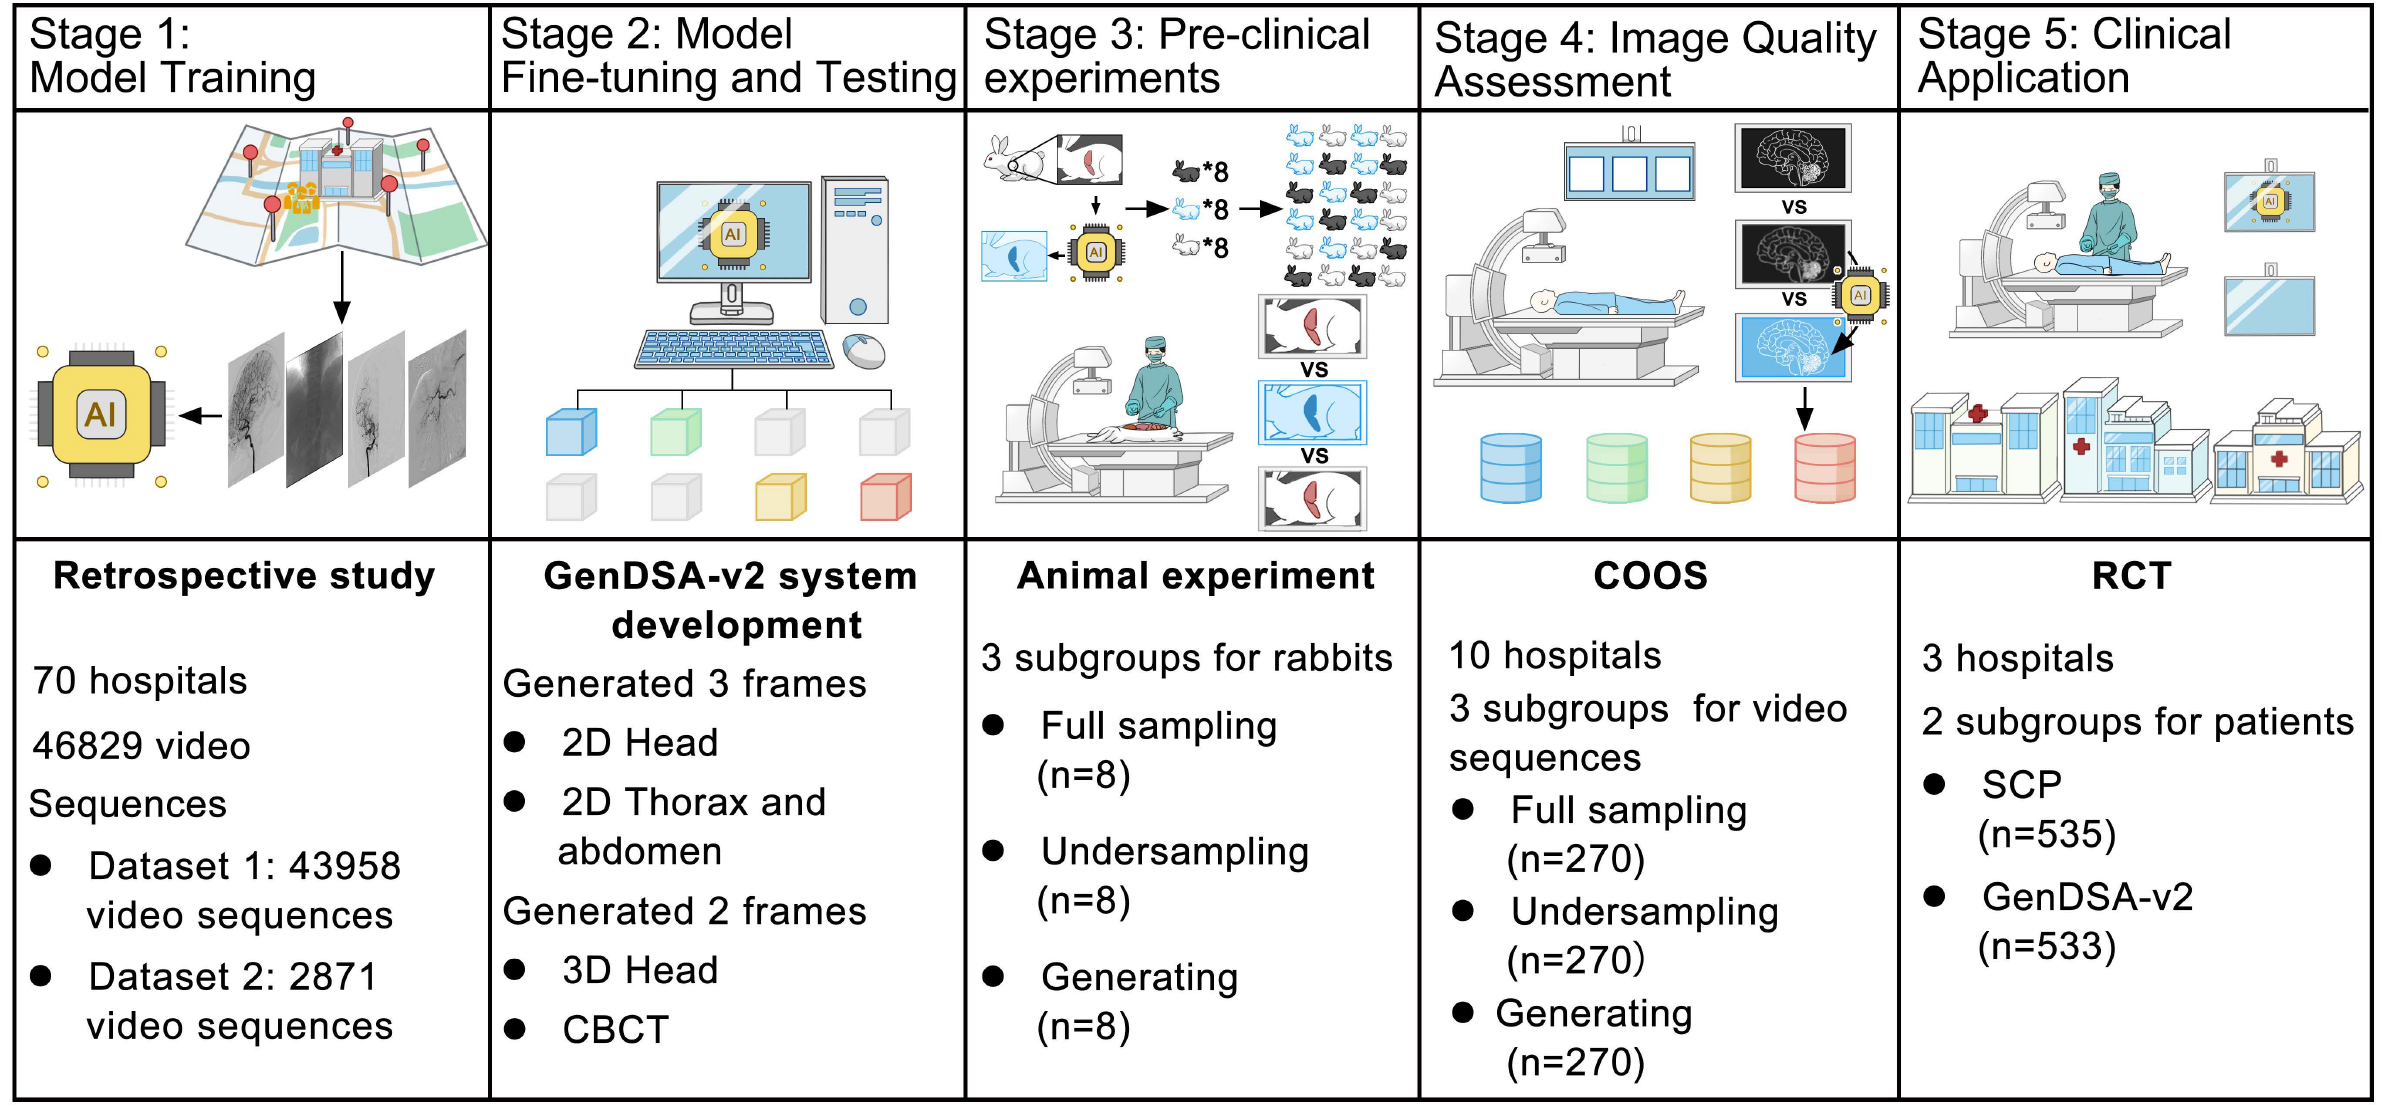
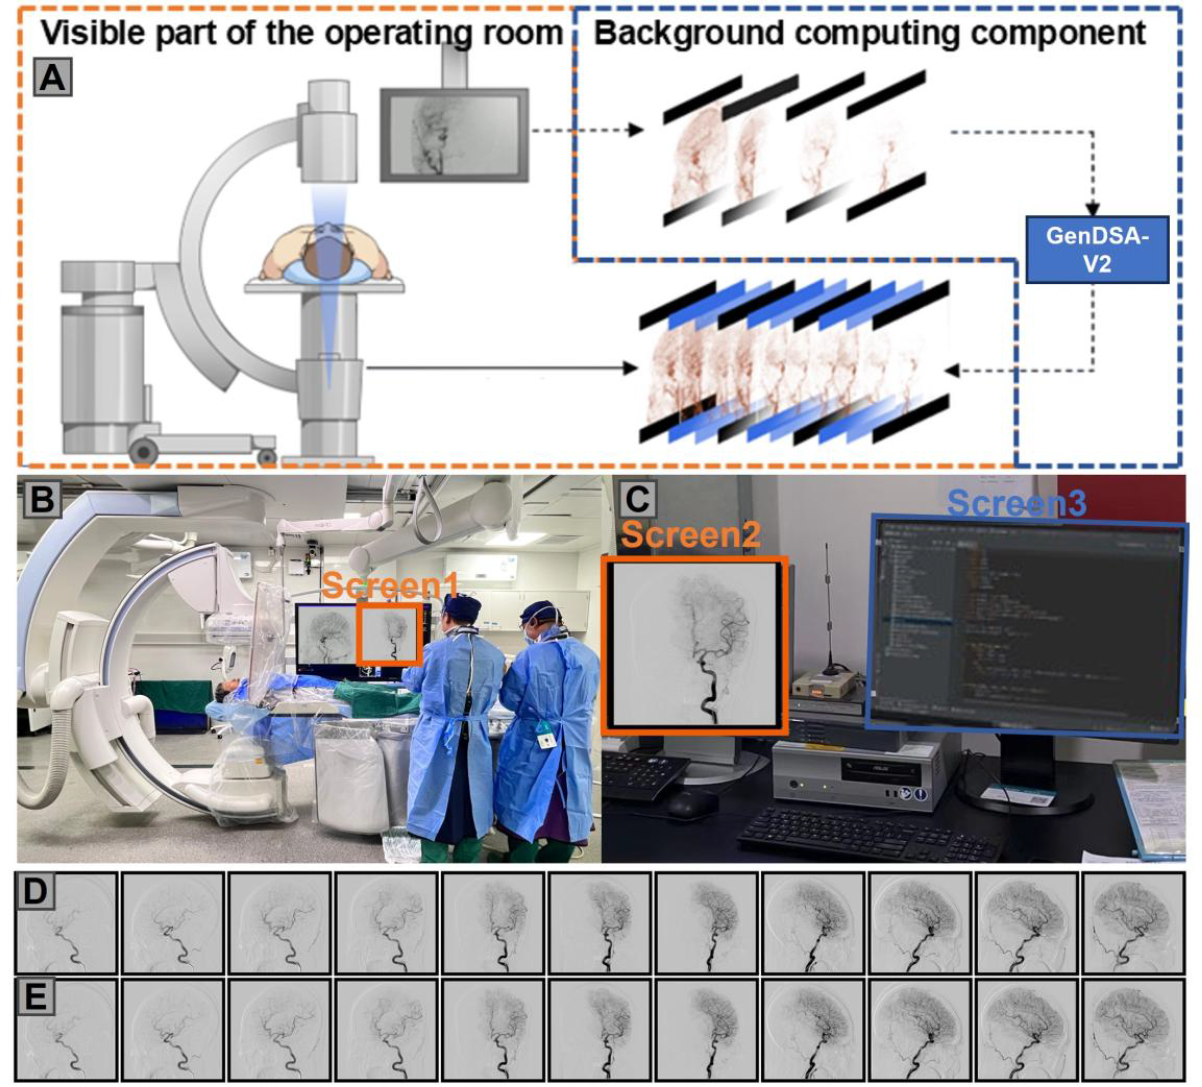
GenDSA-V2 iterates our previously developed GenDSA system using data from 46,829 patients, more than 5 million DSA images, and 70 centers. In a completed prospective randomized controlled trial of 1,068 patients, it reduced radiation exposure for patients and healthcare professionals by approximately two-thirds while maintaining noninferior operation time and similar complication rates. |
|
Representative Work
Large-scale pretrained frame generative model enables real-time low-dose DSA imaging: An AI system development and multi-center validation study* Equal contribution
Role: Co-first Author · Algorithm Lead
GenDSA is a large-scale pretrained multi-frame generative system for real-time low-dose DSA imaging. It was developed on approximately 3 million DSA images from 27,117 patients at 10 hospitals and evaluated on two additional datasets from 25 hospitals; using one-third of the clinical radiation dose, it generated frames in 0.07 seconds and achieved image quality comparable to full-sampled videos. |

|
GaraMoSt: Parallel Multi-Granularity Motion and Structural Modeling for Efficient Multi-Frame Interpolation in DSA ImagesRole: First Author
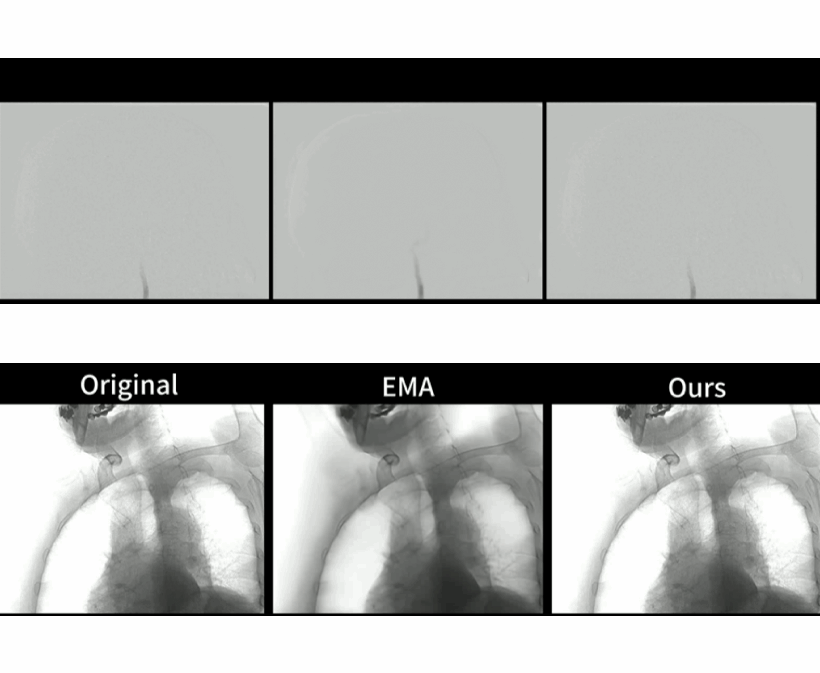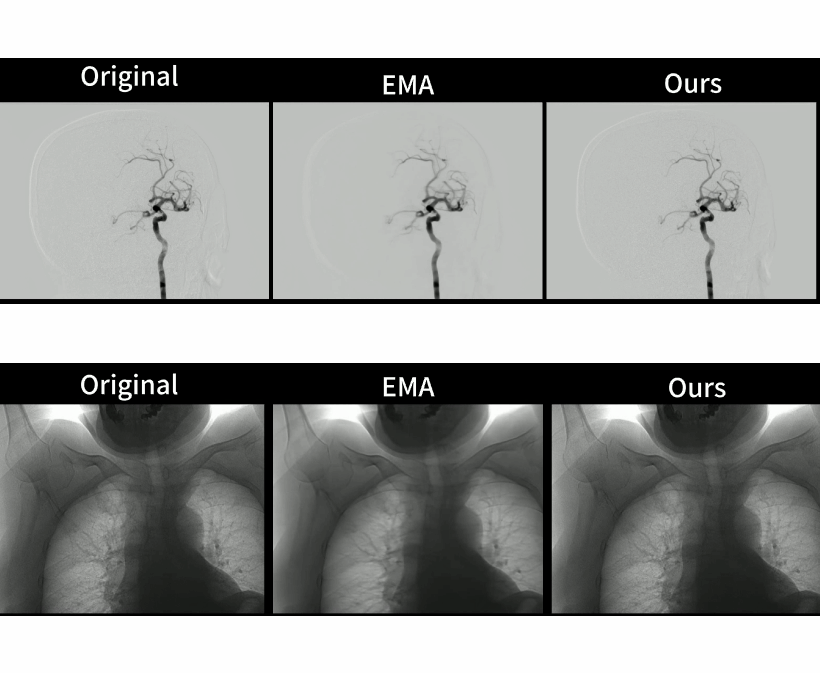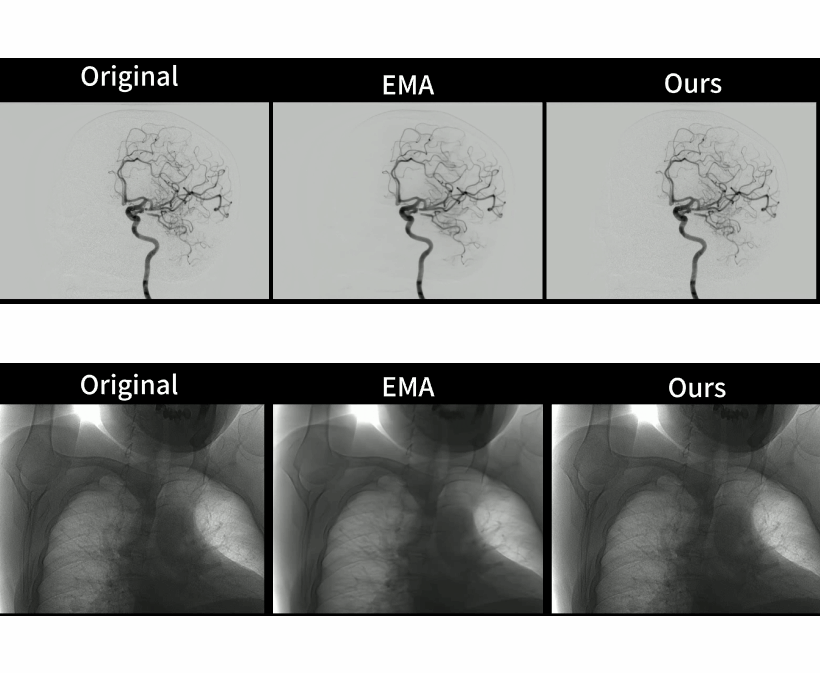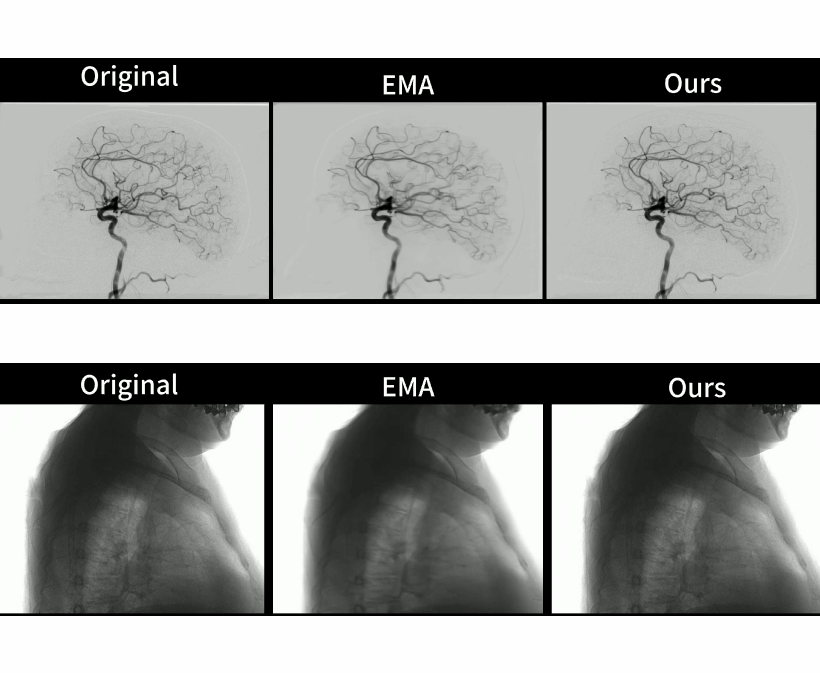
GaraMoSt extends MoSt-DSA with parallel multi-granularity motion and structural feature extraction. The design improves noise suppression, accuracy, and visual quality within the same computational time scale, outperforming MoSt-DSA and natural-scene video frame interpolation baselines on DSA interpolation. |
|
MoSt-DSA: Modeling Motion and Structural Interactions for Direct Multi-Frame Interpolation in DSA ImagesRole: First Author
MoSt-DSA is the first deep learning method designed specifically for DSA frame interpolation. It models motion-structure interactions and directly generates an arbitrary number of intermediate frames at arbitrary time steps in a single forward pass, establishing the algorithmic foundation for the subsequent GaraMoSt and GenDSA systems. |
Internship
Research Intern, vivo AI Lab
Worked on efficient & high-performance on-device image inpainting and multimodal content generation, covering large-scale pre-training and distillation, with a focus on lightweight architecture design and optimization for both performance and efficiency. This work led to PixelHacker and Moebius.
|
Selected Honors & Awards
Outstanding Ph.D. Student, Huazhong University of Science and Technology (华中科技大学三好研究生,博士), 2026.
Outstanding Master’s Graduate, Huazhong University of Science and Technology (华中科技大学优秀毕业生,硕士), 2025.
National Scholarship for Graduate Students (Master’s Level) (研究生国家奖学金,硕士), 2024.
Awarded to only 0.2% of candidates nationwide.
Outstanding Graduate Student, Huazhong University of Science and Technology (华中科技大学三好研究生,硕士), 2024.
Outstanding Graduate, Wuhan University of Technology (武汉理工大学优秀毕业生,本科), 2022.
Provincial Undergraduate Innovation and Entrepreneurship Training Program — Excellent Completion (优秀结题), 2021.
Team Lead “Research and Implementation of a Video-Based Vehicle-Assisted Driving Device.”
Outstanding Undergraduate Student, Wuhan University of Technology (武汉理工大学三好学生,本科), 2021.
|
Selected Competitions
Team Lead Huawei Cup 19th China Graduate Mathematical Modeling Competition (华为杯第十九届中国研究生数学建模竞赛), National Second Prize (国家级二等奖), 2022.
Top 13% (前13%) of all teams.
Team Lead Artificial Intelligence Track of the 14th China College Student Computer Design Competition (中国大学生计算机设计大赛人工智能赛道), National Third Prize (国家级三等奖), 2021.
Among the 4,886 entries that advanced from the provincial round to the national competition, 8.5% received this award.
National College Student Integrated Circuit Innovation and Entrepreneurship Competition (全国大学生集成电路创新创业大赛), Third Prize in Hubei Province (湖北省三等奖), 2021.
Team Lead The 20th Innovation Cup College Students Extracurricular Academic Science and Technology Works Competition (创新杯大学生课外学术科技作品竞赛), Special Prize (特等奖) in the Mathematical Information Group (数理信息组), 2020.
I led the team to win the sole Special Prize (唯一特等奖) in the Mathematical Information category.
Team Lead National College Student Mathematical Modeling Competition (全国大学生数学建模竞赛), Second Prize in Hubei Province (湖北省二等奖), 2020.
|
Academic ServiceConference Reviewer: CVPR 2026; ECCV 2026/2024.
Journal Reviewer: IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI), 2026; Image and Vision Computing, 2026; International Journal of Computer Vision (IJCV), 2024.
|